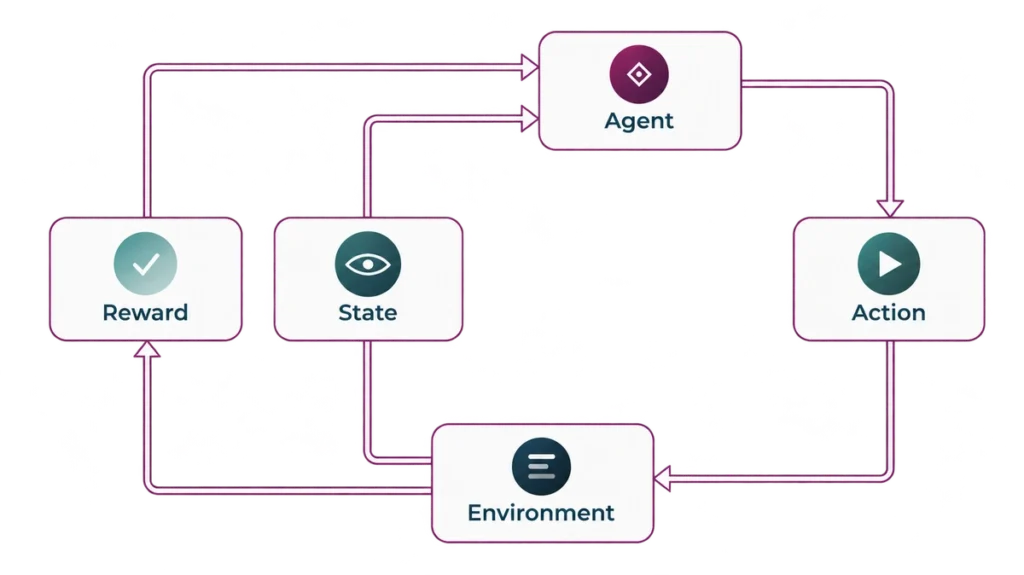
Multilingual RL environments and agentic evaluation.
Runnable multilingual environments for long-horizon agent work. Tasks, harness, verifier and expert-defined scoring criteria, built with practitioners who know the work, language, and local context.
Many widely used agent environments center on English-language or coding workflows. Evaluating work in another language or jurisdiction can require more than translating an existing task.
THE STATE OF LONG-HORIZON AGENTS
What the published benchmarks show.
Recent research benchmarks show substantial performance gaps on realistic, multi-step professional work. They also show why evaluating these tasks can require more than a single pass/fail score at the end.
30%
Best autonomous task completion
TheAgentCompany evaluates agents in a simulated workplace across software engineering, project management, data science, HR, finance and administration. The strongest agent reported in the published study completed 30% of tasks autonomously.
36.2%
Best strict pass rate
HANDBOOK.md evaluates agents on professional workflows governed by long operating procedures across finance, medical billing, insurance, logistics and HR. The strongest reported configuration passed 36.2% of trials under strict grading; most frontier configurations remained below 25%.
824
Criteria used to evaluate 65 tasks
HANDBOOK.md uses 824 programmatic rubric criteria to check required and prohibited actions across its 65 tasks. TheAgentCompany similarly evaluates task outcomes against intermediate checkpoints. These benchmarks illustrate why long-horizon evaluation can benefit from criterion-level scoring rather than relying only on binary task completion.
Results are not directly comparable across benchmarks; tasks, models, agent scaffolds and scoring methods differ. Sources: Xu et al., TheAgentCompany: Benchmarking LLM Agents on Consequential Real World Tasks, NeurIPS 2025; Panavas et al., HANDBOOK.md: Are Agents Ready for Real-World Enterprise Tasks?, 2026.
THE MULTILINGUAL PROBLEM
A translated task is not
a native multilingual task.
Translation can carry over the language of a task. It does not by itself recreate jurisdiction-specific workflows, systems, sources or regulations. When those elements matter to the work being evaluated, they have to be represented in the environment.
OPTION 01
English task, English rubric
Evaluates performance on the original task and workflow.
No evidence yet about other languages or jurisdictions
OPTION 02
English task, translated
The language changes, but the underlying workflow may not. Filing formats, approval chains, authoritative sources and accepted documents can differ across jurisdictions.
Tests multilingual performance on the original workflow
OPTION 03
Authored for the target language and jurisdiction
Domain experts define the professional workflow, including the evidence, rules and actions that matter for successful completion.
Tests performance in the target workflow
- What has to stay aligned
- The task, evidence and scoring criteria have to describe the same workflow. If localization changes the documents, rules or expected actions without updating the evaluation criteria, a model can be rewarded for behavior that would not be correct in the target setting.
- Why locale counts are not enough
- Supporting a language does not by itself establish coverage of the professional workflow. Jurisdiction-specific rules, documents, systems and practices may also need to be represented in the environment and its evaluation criteria.
THE UNCHECKED HALF
Building the environment is only half the evaluation problem.
Connector counts, task counts, personas and harness design tell you what an agent can interact with. An equally important question is what constitutes success: which outcomes, actions and intermediate states are scored, and on what basis.
A single right-or-wrong score at the end of a thirty-step workflow doesn’t tell you whether the agent missed a required source, made a bad call midway, took an invalid action, reached the right answer for the wrong reason, or hit an artifact of the environment that was never a real failure. Distinguishing those cases requires evaluation criteria that reflect how the work is actually done.
Answer
Did the agent reach the decision a qualified professional would defend?
Resulting state
Do the records, documents and workflow reflect what the agent claims it did?
Policy compliance
Did it respect permissions, approval gates and prohibited actions?
Path taken
Did it gather the required evidence and take the necessary actions in a way that holds up to review?
WHAT YOU GET
Everything needed
to run it yourself.
01
Task design
Multi-step tasks designed to test consequential capabilities, tiered by difficulty.
02
Environment and harness
Tool surfaces, state, episode reset and action logging.
03
Rubrics, verifier, and scoring logic
Expert-defined criteria for full, partial and failed task completion, backed by deterministic checks and partial credit where the task supports meaningful intermediate success.
04
Model trajectories
Full step-by-step runs with criterion-level scoring attached.
05
Baseline reporting
Performance on selected models, with the model, setup and scoring methodology documented.
THE SAMPLE PACK
Five full tasks, containerized, running on your side
- Five complete tasks, not excerpts
- Containerized environments in open formats, ready to run
- Verifier and expert rubrics
- Reference solutions, tasks are verifiably solvable
- Trajectories and pass rates of relevant models
HOW WE BUILD IT
The evaluation is designed with the environment.
Evaluation starts during task and environment design, not after them. If the scoring criteria require evidence, state changes or intermediate actions that the environment does not capture, adding the rubric later can mean rebuilding the task.
STEP 1
Author where the workflow lives
Practicing experts help define the workflow in the target language and jurisdiction, grounded in authoritative sources, professional practice, and task-specific evidence.
STEP 2
Separate authoring from validation
Where appropriate, task authors and validators are separated so assumptions in the original task design can be independently challenged.
STEP 3
Design evaluation during environment construction
Define what evidence the agent must find, which state changes matter, which actions are required or prohibited, and where partial credit is meaningful. The environment has to make those criteria observable.
STEP 4
Hold out an evaluation set
A portion of cases and combinations is kept unseen during development, so performance can be measured on work the model did not encounter during training or tuning.
WHERE THE DATA COMES FROM
Every vendor tells you what is in the environment. Ask where the material came from.
Four sources, ordered by authenticity. Environment data can come from several sources, often in combination. The right mix depends on the target workflow, access constraints, privacy requirements and evaluation goal. Whatever the source, the task and scoring criteria still need to reflect the professional workflow being evaluated.
01
Real third-party company data
Existing organizational data can provide realistic structure and complexity, but are difficult to source and can introduce privacy, licensing, custody and governance constraints.
02
Customer-supplied workflow data
The customer’s own records, documents, and workflows can provide high relevance to the intended deployment, subject to access, privacy and governance requirements.
03
Expert-constructed environments
WHAT WE USE FOR MULTILINGUAL WORK
We build realistic cases and environments around workflows defined and validated with domain experts, using representative schemas, document formats, constraints and operational logic. The records can be constructed while the task structure and evaluation criteria remain grounded in professional practice.
04
Synthetic generation
Synthetic data can efficiently create controlled variation, edge cases, and scale. Its value depends on how generation is constrained and how the resulting tasks and evaluation criteria are validated.
WHO WE BUILD FOR
Three buyers,
three shapes of the same problem.
Translation can carry over the language of a task. It does not by itself recreate jurisdiction-specific workflows, systems, sources or regulations. When those elements matter to the work being evaluated, they have to be represented in the environment.
Frontier labs
Building environments and evaluation data to train and measure agents on complex professional workflows.
Expert-constructed tasks · multilingual coverage
Enterprises
Testing agents against realistic versions of the business workflows they are expected to handle, with domain experts defining what successful performance looks like.
Business workflows · expert-defined evaluation
Sovereign and multilingual builders
Building and evaluating agents for languages, jurisdictions and workflows that remain underrepresented in public benchmarks.
Multilingual environments · local expertise
INTEGRATION
Thin and switchable,
not trivial.
Building a runnable environment is real engineering: tool surfaces, state, episode control and logging. We aim to keep the task and evaluation assets separable from the surrounding infrastructure rather than requiring customers to adopt a proprietary platform. Delivery can support interoperable environment formats such as Harbor or OpenEnv, depending on the engagement.
A core part of the value is the professional judgment encoded into the tasks and evaluation criteria. Those assets should remain useful beyond any single harness.
THE OPERATION UNDERNEATH
155+
Locales with sourced, vetted expertise
8
Global regions of delivery operations
14
Secure facilities with access control
SLA
Backed delivery, with a quality management system behind it
Nobody should get less out of AI because of the language they were born speaking.
That starts with measuring whether it works there.
Send us the workflow and the language.vWe will send back something you can run.
Five complete, containerized tasks with model trajectories, expert-defined scoring criteria and documented baseline results.